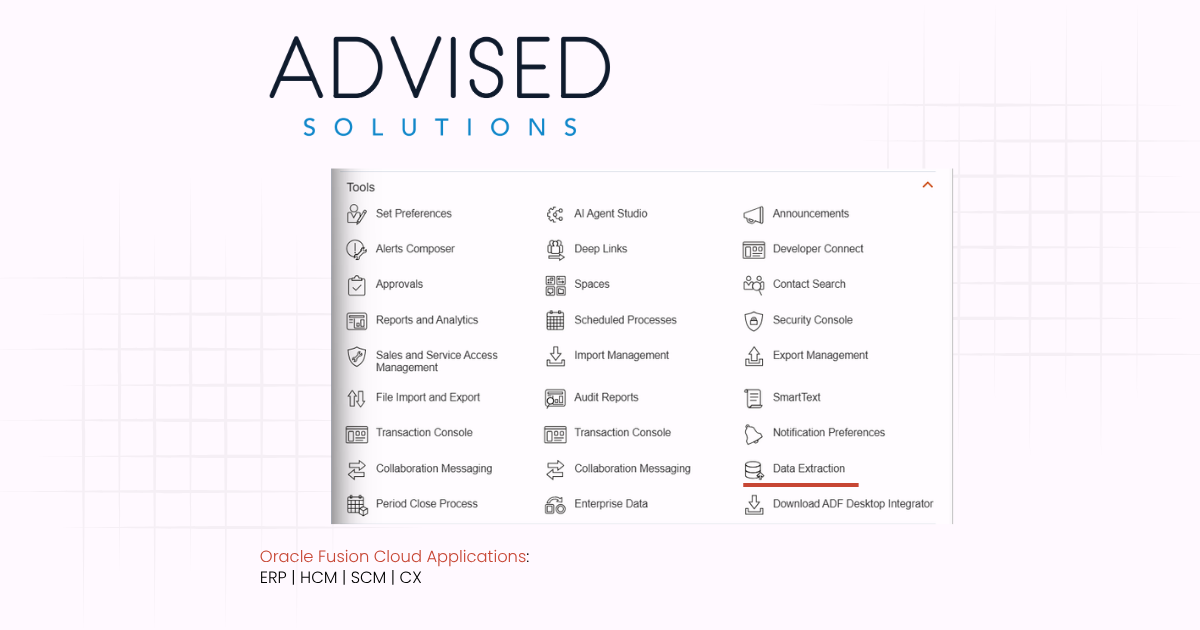

Oracle Fusion’s Data Extraction Tool: A Modern, Secure Way to Get Data Out
Oracle Fusion’s new Data Extraction tool is a Redwood‑based, self‑service utility for securely extracting large volumes of application data from a Read‑Optimised Data Store, designed as the long‑term successor to BICC. It emphasises performance, simplicity, and governance, making it a strong fit for bulk reporting, integrations, and data pipelines.
What the Tool Is (and Why It Matters)
The tool extracts data from Oracle Fusion Cloud Applications via a read‑optimised data store replicated into Oracle Autonomous AI Lakehouse, rather than querying the transactional database directly. This architecture delivers very high performance for bulk extracts, keeps load off the core applications, and exposes data through clean business object and extraction views. Oracle positions it as the modern replacement for BICC, with a Redwood UI, improved incremental support, and far less impact on the applications database.
How It Compares to BICC
Versus BICC, the New Data Extraction tool offers:
Performance: Medium → Very High.
Schema complexity: Complicated views → Clean business object views.
Incremental support: Limited → Full and optimised.
Application load: High → Near‑zero.
User experience: Legacy → Redwood.
Enabling the Data Extraction Tool
The feature is off by default and must be opted in.
- Setup and Maintenance → Manage Administrator Profile Values:
ORA_ASE_SAS_INTEGRATION_ENABLED at Site level = Yes.
Create a custom role (e.g. DataExtractRole) and assign:
- ESSAdmin
- OBIA_EXTRACTTRANSFORMLOAD_RWD
- ORA_RCS_SUPPLY_CHAIN_INTEGRATION_SPECIALIST_JOB
Then assign the role to users.
Using the Tool: Definitions, Schedules, Jobs, Metadata and Output
The UI is organised around three areas:
Extract Definitions – what to extract and how.
Extract Schedules – when to run it.
Extract Jobs – monitoring and retrieving outputs.
To create an extract: define a name, choose CSV or JSON, select a pillar and functional area, pick an object (e.g. Sales Orders Extract), choose attributes, and optionally add filters. Schedules can be one‑off or recurring; jobs show status (Paused, Running, Succeeded, Failed). Completed extracts are written securely to UCM, where you retrieve them by Request ID from Checked Out Content.
Each run produces:
A data file (CSV/JSON) with the selected records.
A metadata file with fields such as EXTRACT_NAME, JOB_TYPE, date range, row counts, STATUS, and ERROR_MESSAGE.
This supports audit, reconciliation, and automated error handling in data pipelines.
Migrating away from BICC
For organisations dependent on BICC, you have the ability to apply BICC column headers to the Data Extraction views and attributes, this provides a clear migration path with better performance and a more maintainable data model.
Need some assistance?
Ready to simplify how you extract high volumes of data from Oracle Fusion? Whether you’re building new bulk extracts or migrating existing BICC jobs to Oracle’s next‑generation Data Extraction tool, we specialise in designing, securing, and optimising extraction workflows that are fast, reliable, and easy to maintain. From selecting the right business views and filters to implementing robust scheduling and monitoring, we help you deliver clean, governed data feeds for your data warehouses, data lakes, and analytics platforms. Contact us today to discover how our expertise in Oracle Fusion data extraction can reduce runtimes, lower application load, and future‑proof your integration and reporting landscape.